Himel3
A model that
digs deeper.
Himel3 is a new language model from Philiaxis, the maker of Himel Agent.

The deeper you dig,
the deeper it goes.
Himel3 is a model that does not hurry its answers. It separates the question into layers and only speaks once it has reached the reasons underneath.
What changed on arithmetic tasks
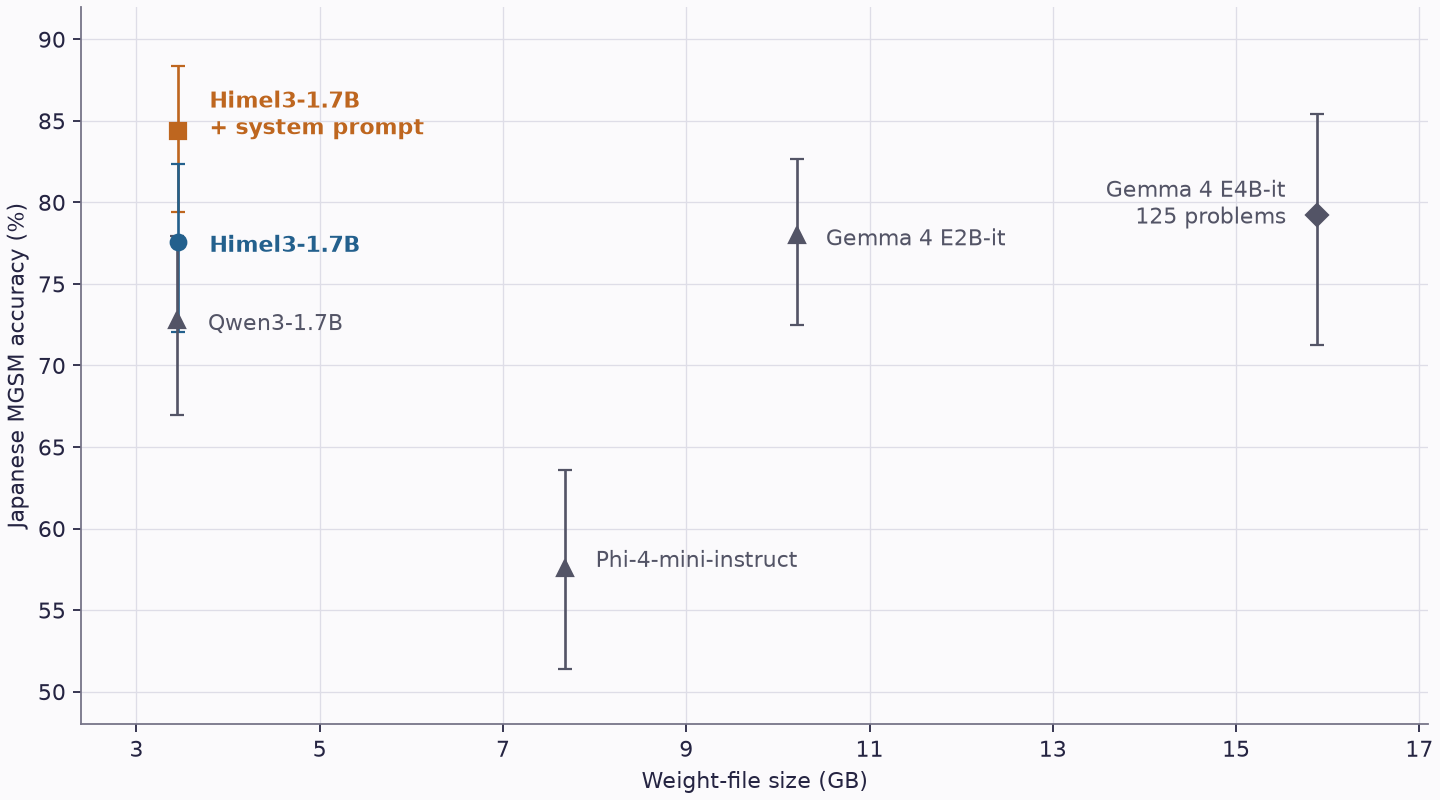
Adding a system prompt to Himel3-1.7B raised Japanese MGSM accuracy from 77.6% to 84.4% (+6.8 percentage points, paired McNemar p=0.0046). English MGSM went from 92.8% to 94.0%.
Scroll the table horizontally for more columns.
| Model and configuration | Japanese (%) | English (%) | Mean output tokens (Japanese) | Output limit reached (Japanese, %) |
|---|---|---|---|---|
| Himel3-1.7B | 77.6 [72–82] | 92.8 [89–95] | 1,627 | 5.2 |
| Himel3-1.7B + system prompt | 84.4 [79–88] | 94.0 [90–96] | 1,478 | 1.2 |
| Himel3-1.7B-graft | 78.4 [73–83] | 94.4 [91–97] | 1,708 | 4.8 |
| Himel3-1.7B-graft + system prompt | 82.4 [77–87] | 94.4 [91–97] | 1,564 | 4.8 |
| LFM3-1.7B | 75.6 [70–81] | 93.6 [90–96] | 1,859 | 6.0 |
| Qwen3-1.7B | 72.8 [67–78] | 92.4 [88–95] | 1,980 | 3.2 |
| Gemma 4 E2B-it | 78.0 [72–83] | — | 989 | 0.0 |
| Gemma 4 E4B-it | 79.2 [71–85] (n=125) | — | 914 | 0.0 |
| Phi-4-mini-instruct | 57.6 [51–64] | — | 346 | 0.0 |
250 problems per language, except Gemma 4 E4B-it in Japanese (125). Brackets show 95% Wilson confidence intervals. A dash marks an evaluation without a completed result.
 Enlarge chart
Paired comparisons on the same problems
On the same 250 Japanese problems, Himel3-1.7B with a system prompt scored 11.6 percentage points higher than Qwen3-1.7B (84.4% versus 72.8%, p=0.000015) and 6.4 points higher than Gemma 4 E2B-it (78.0%, p=0.0090).
On the 125 problems completed by Gemma 4 E4B-it, Himel3-1.7B with a system prompt scored 82.4% and E4B-it scored 79.2% (p=0.45). On all 250 problems, the graft variant scored 82.4% with a system prompt and 78.4% without one. The difference between the standard and graft variants with the system prompt was statistically inconclusive (p=0.40).
Evaluation method and known limits
For the rows labeled “+ system prompt”, the system message was You are a helpful assistant trained by Liquid AI.
We ran the evaluations in MLX on an Apple M1 Max (32 GB), using each model’s own chat template and enabling thinking where supported. We sampled at temperature 0.6 and top-p 0.95 with an output limit of 8,192 tokens, grading the last boxed answer or, if there was none, the final number.
Models ran in bf16, with Phi-4-mini-instruct in fp16. Qwen3.5 runs did not finish in this setup. The comparison covers arithmetic. We did not evaluate tool use, long context, agent workflows, knowledge questions, or long-document understanding.
Himel3-1.7B scored 86.7% on the 300-problem Japanese GSM8K development set, which we also used during tuning.
Himel3-1.7B reached the output limit on 5.2% of Japanese problems and 2.4% of English problems without a system prompt. With one, those rates were 1.2% and 1.6%.
Models and license
Himel3-1.7B and Himel3-1.7B-graft use the LFM Open License v1.0. Both derive from Liquid AI’s LFM3-1.7B.